Async cancellation and sync blocks: good luck debugging this
The Setup: Code That Worked for Years#
Imagine having such code:
use rand::Rng;
use std::collections::HashMap;
use std::sync::{Arc, Mutex};

// let's pretend it's a realprod db which manages its synchronization on its own
struct Db {
    data: Mutex<HashMap<u32, u32>>,
}

impl Db {
    // recursive function where current value depends on the previous one so it's easy to find coruptions
    fn compute_next(&self, round: u32) -> u32 {
        let mut data = self.data.lock().unwrap();

        let prev_value = match round.checked_sub(1) {
            Some(prev_round) => *data.get(&prev_round).unwrap_or(&0),
            None => 0,
        };

        let result = prev_value + 1;
        data.insert(round, result);
        result
    }

    fn snapshot(&self) -> HashMap<u32, u32> {
        self.data.lock().unwrap().clone()
    }
}

struct Worker {
    db: Db,
    // lock to ensure that only single thread calls `heavy_compute` at a time
    mutex: tokio::sync::Mutex<()>,
}

impl Worker {
    async fn frob(self: &Arc<Self>, round: u32) -> Result<()> {
        let _lock = self.mutex.lock().await;
        {
            let this = self.clone();
            tokio::spawn_blocking(move || this.heavy_compute(round)).await?;
        }
    }

    /// Must be called while lock is held.
    /// Updates kv entry in realprod db.
    fn heavy_compute(&self, round: u32) -> Result<()> {
        // Simulate expensive computation
        std::thread::sleep(Duration::from_secs(rand::thread_rng().gen_range(1..3)));
        self.db.compute_next(round);

        Ok(())
    }
}

async fn main_loop() {
    let worker = Worker::default();

    for i in 0..100 {
        let res = worker.frob(i).await;
        // process result
    }
}
You have some function, which has precondition to being called serially. Function takes a lot of time, eating your precious cpu time, so you spawn it on separate thread to mitigate blocking of runtime.
Code worked for years without issues, everybody was happy. This calculation was core of your company.
The Change: Adding a Fast Path#
Some day you found that you can actually query some other resource to get this value - eg other cache server.
So your main loop now looks like this:
async fn main_loop() {
    let worker = Worker::default();

    for i in 0..100 {
        let fut1 = fetch_cached(i);
        let fut2 = worker.frob(i);

        let res = tokio::select!(fut1, fut2);
        // process result
    }
}
Heads-up: when
tokio::select!picks one branch, the other future is dropped immediately - jj releasing any resources it owned (e.g., async mutex guards).
The Mystery: Inconsistent Results#
You run tests(you have them, right?) and found that your precious calculations are incorrect - sometime calculations for n are right, some time they show stale values. You blame your realprod db for stale caches or something.
heavy_compute was working for years, nobody have changed anything in it.
The Investigation: Adding Assertions#
Desperate, you modify it to shed some light:
fn heavy_compute(&self, round: u32) -> Result<()> {
    let before = self.db.snapshot();

    // Simulate expensive computation
    std::thread::sleep(Duration::from_secs(rand::thread_rng().gen_range(1..3)));
    let after = self.db.snapshot();

    assert_eq!(
        before, after,
        "db state was changed despite mutex being held"
    );
    self.db.compute_next(round);

    Ok(())
}
and find out that you have different data from what you have read on the start of computation. Assert fires 1 time in an hour.
You call author of heavy_compute, asking him why it stopped working.
You check all the code, it looks correct.
Mutex is being held during while heavy_compute is called.
Hoplessly you change heavy compute one more time:
fn heavy_compute(round: u32, sync_mutex: std::sync::Mutex<()>) -> Result<()> {
    let _lock = sync_mutex.lock();
    // rest of the code
}
Magicaly assert stops firing. All is green.
This feels like a fix, but it's really just a clue.
We've papered over the race condition by forcing all blocking tasks to run one at a time, but we haven't addressed the root cause:
why we even have the spawn_blocking tasks running in parallel if we have a mutex?
The Root Cause#
So, what's the problem?
cancellation.
frob is canceled when fetch_cached runs faster then heavy_compute.
When tokio::select! cancels frob, it drops the future's state - including the mutex guard - but the spawned thread keeps running.
Timeline:#
T0: Task A acquires async mutex for round 5
T1: Task A spawns blocking thread for round 5
T2: Task A gets cancelled (select! chooses the cache path)
T3: Async mutex is released (guard dropped)
T4: Task B acquires async mutex for round 6
T5: Task B spawns blocking thread for round 6
T6: Both threads are now running heavy_compute() simultaneously!
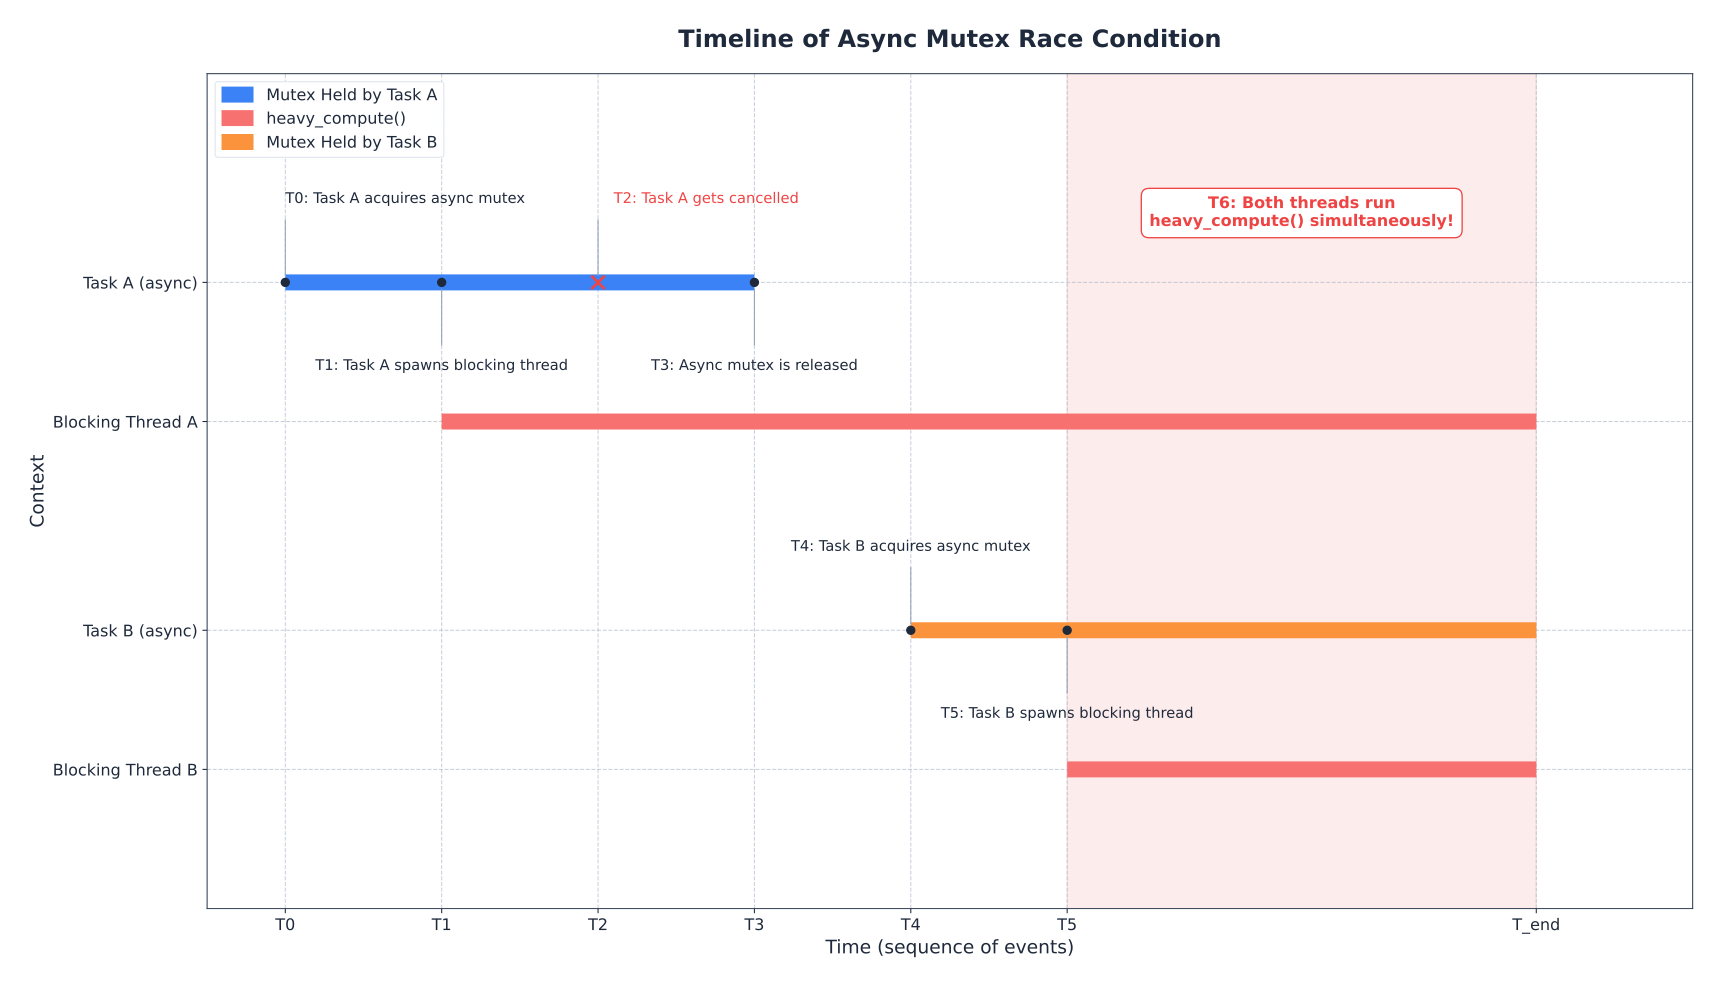

How Async Cancellation Works#
Click to see state machine desugaring
Lets rewrite our async fn as state machine.
enum FrobState {
    Start {
        this: Arc<MyStruct>,
        round: u32,
    },
    Locking {
        lock_future: MutexLockFuture,
        this: Arc<MyStruct>,
        round: u32,
    },
    Computing {
        _lock: MutexGuard,
        rx: oneshot::Receiver<Result<()>>,
    },
    Done,
}

use std::mem;
use std::task::{Context, Poll};

// This function represents the simplified work a runtime's executor does.
fn poll(state: &mut FrobState, cx: &mut Context<'_>) -> Poll<Result<(), ()>> {
    loop {
        // Take ownership of the current state, leaving a placeholder.
        let current_state = mem::replace(state, FrobState::Done);

        match current_state {
            // --- Before the first .await ---
            FrobState::Start { this, round } => {
                // Create the future for the first .await.
                let lock_future = this.mutex.lock_async();

                // Transition to the next state.
                *state = FrobState::Locking {
                    lock_future,
                    this,
                    round,
                };
            }

            // --- Polling the first .await ---
            FrobState::Locking {
                lock_future,
                this,
                round,
            } => {
                match lock_future.poll(cx) {
                    Poll::Pending => {
                        // The lock is not ready. Put the state back.
                        *state = FrobState::Locking {
                            lock_future,
                            this,
                            round,
                        };
                        // Return Pending, indicating the future is not complete.
                        return Poll::Pending;
                    }
                    Poll::Ready(guard) => {
                        // Lock acquired.
                        let (tx, rx) = oneshot::channel();
                        let this_clone = this.clone();

                        thread::spawn(move || {
                            let result = this_clone.heavy_compute(round);
                            let _ = tx.send(result);
                        });

                        // Transition to the next state
                        *state = FrobState::Computing { _lock: guard, rx };
                    }
                }
            }

            // --- Polling the last .await ---
            FrobState::Computing { _lock, mut rx } => {
                // Poll the receiver future.
                match rx.poll(cx) {
                    Poll::Pending => {
                        // The result is not ready. Put the state back.
                        *state = FrobState::Computing { _lock, rx };
                        return Poll::Pending;
                    }
                    Poll::Ready(result) => {
                        // The async function is now complete.
                        // The `_lock` guard from `current_state` is dropped here,
                        // releasing the mutex. `state` is already `Done`.
                        return Poll::Ready(result);
                    }
                }
            }

            // --- Final state ---
            FrobState::Done => {
                panic!("FrobState polled after completion");
            }
        }
    }
}
tokio::select! can be viewed as such loop(without context, wakers and all this stuff):
let fut1 = FrobState::Start { this, round };
let fut2 = fetch_cached(round);

loop {
    let fut1_state = poll_frob(&mut fut1);
    let fut2_state = poll_cache(&mut fut2);

    if let Poll::Ready(res) = fut1_state {
        return res;
    }

    if let Poll::Ready(res) = fut2_state {
        return res;
    }

    // In a real polling loop, you'd yield if neither is ready, but we simplify it here.
    }
So when either fut1 or fut2 completes other future is dropped. Including it's lock. But nobody cancels thread spawn!
It's still working in background, not knowning thats nobody waits for it's result and more importantly not knowning that it's not protected by lock!
The Solution: Owned Guards#
Acquire blocking mutex handle.
struct Worker {
    db: Db,
    mutex: Arc<tokio::sync::Mutex<()>>,
}

impl Worker {
    async fn frob(self: &Arc<Self>, round: u32) -> Result<()> {
        let lock = self.mutex.clone().lock_owned().await;
        {
            let this = self.clone();
            tokio::spawn_blocking(move || this.heavy_compute(round, lock)).await?;
        }
    }

    /// Must be called while lock is held.
    /// Updates kv entry in realprod db.
    fn heavy_compute(&self, round: u32, _lock: OwnedMutexGuard) -> Result<()> {
        // .. previous code
    }
}
Instead of being stored in the async fn's state (which can be dropped at any .await point during cancellation), we can move ownership of this guard directly into the closure given to spawn_blocking. Now, the lock's lifetime is tied to the blocking task itself. The lock will only be released when the blocking thread finishes its work, regardless of whether the original frob task that spawned it was cancelled.
The same thing applies for tokio::fs functions. Eg
fs::read(some_huge_file)can linger when caller is cancelled.
Runnable code for the article here